Key Takeaways
Axe Compute now has a multi-year strategic partner: Axe signed Penguin Solutions to speed up Axe Compute Build, its build-to-order program, as it works to bring more than $3.45 billion in contracted customer AI infrastructure projects into production.
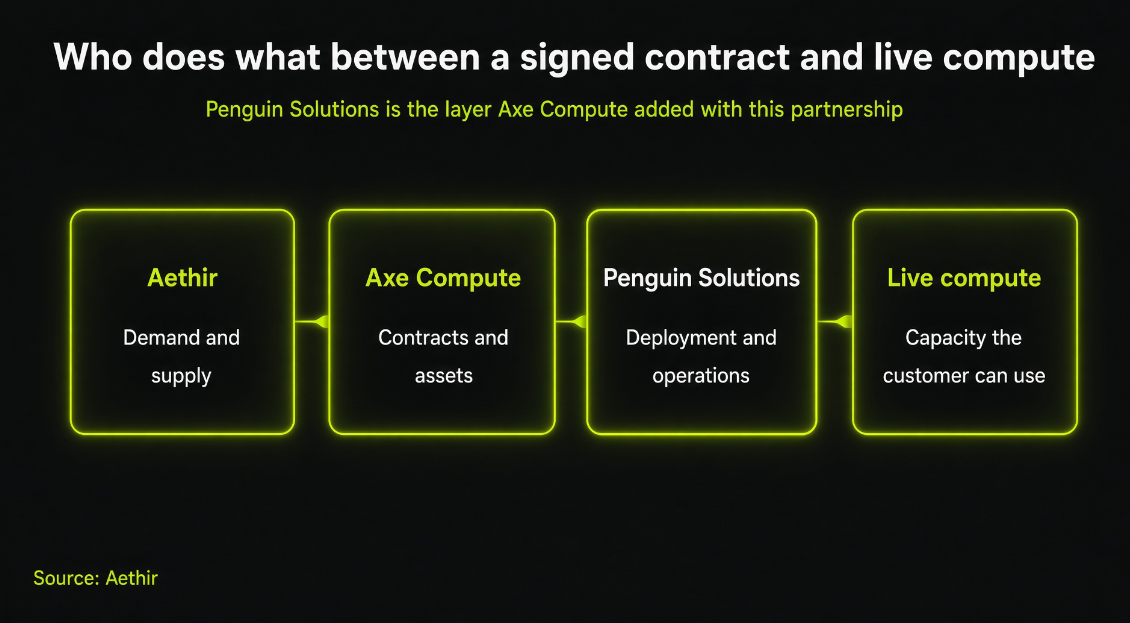
Penguin Solutions will support multiple sites with deployment and operational services, its ClusterWareAI operating system software, and 24x7 network operations center coverage. Axe keeps the customers and the assets.
Penguin’s track: Penguin Solutions has deployed and managed more than 89,000 GPUs and logged over 33 billion hours of GPU runtime across HPC and AI infrastructure.
Haein is the closest reference build: Penguin built and still runs Haein, a sovereign AI cluster for SK Telecom, one of the largest in Korea, production-ready within weeks of the hardware arriving.
Aethir Foundation is Axe Compute’s shareholder: Aethir covers Axe as an interested holder, while Axe Compute is also a key delivery partner for our Aethir ACCELERATE program.
Axe Compute Signs Penguin Solutions as a Strategic GPU Deployment Partner
On October 14, 2026, Axe Compute (NASDAQ: AGPU) announced a multi-year strategic partnership with Penguin Solutions (NASDAQ: PENG) to accelerate Axe Compute Build, its build-to-order program for delivering enterprise-grade AI infrastructure at scale.
Axe Compute says it has more than $3.45 billion in contracted customer AI infrastructure projects to bring into production globally. CEO Christopher Miglino said demand for Axe Compute Build “has been exceptional” and called Penguin Solutions “a natural fit as we scale our neocloud business.”
Axe already owns its first cluster outright: 2,304 NVIDIA B300 GPUs in Columbus, Georgia, under a customer agreement extended to five years.
Penguin’s team will work alongside Axe Compute on deployment and day-to-day operations for specified GPU cluster sites.
Penguin Solutions: 25 Years of HPC and AI Infrastructure
Penguin Solutions is Nasdaq-listed as PENG, based in Fremont, California. The company has more than 25 years of experience in HPC and AI infrastructure, which matters when capacity must come online on schedule. It calls itself the AI Factory Platform Company and designs, builds, and manages data centers for enterprises, sovereign AI initiatives, and neocloud providers.
Penguin Solutions has already deployed and managed more than 89,000 GPUs, with over 33 billion hours of GPU runtime.
The company helps Meta run more than 2,000 NVIDIA DGX systems and 16,000 A100 GPUs, across a five-year relationship, which is part of the Meta Research SuperCluster.
Furthermore, Penguin Solutions runs SK Telecom Haein, one of Korea’s largest sovereign AI cluster builds, designed and run for GPU-as-a-Service, with 1,032 NVIDIA B200 GPUs and production-ready within weeks of the hardware arriving.
Penguin Solutions is an NVIDIA AI Factory partner under the Specialized Partner designation, an Elite Partner, and a DGX-Ready Managed Services Provider.
Additionally, the company leverages OriginAI architectures that run from 64 GPUs to over 24,000 with DGX B300 support, alongside ClusterWareAI for GPU cluster operations. ClusterWareAI is part of what Penguin brings to the Axe Compute partnership.
Why It Matters
GPU allocation stopped being the bottleneck. Standing up a multi-thousand-GPU cluster and keeping it running is where schedules go, and up to half of 2026 capacity could arrive late.
With Penguin in the build-out, Axe Compute can bring contracted capacity online faster across multiple sites while it still designs, deploys, owns, and operates the infrastructure. Penguin’s 24x7 network operations center team works alongside Axe Compute’s, so Axe can scale its neocloud business without building every capability in-house.
What Penguin takes on: Expert-led deployment and operational services, ClusterWareAI software for managing GPU clusters at scale, and 24x7 network operations center coverage, packaged for neocloud operators.
What Axe Compute handles: Customers, capital, data center capacity, and asset ownership stay with Axe Compute, which acts as the end-to-end partner and orchestrator on each Axe Compute Build project.
What repeats: The same AI factory deployment process runs at each new site instead of being rebuilt, which is how GPU cluster operations scale.
Where Aethir Fits
Aethir is part of the demand and supply end of this chain. The network spans 94 countries with 150+ enterprise clients, and has generated more than $166 million in total network revenue since launch.
Axe Compute is a customer of that network and a delivery partner in the Aethir ACCELERATE program. Aethir Foundation is also a shareholder in Axe Compute.
The next real checkpoint is a site coming online with Penguin Solutions supporting it, on a date the market can check.
The full announcement sits on the Axe Compute newsroom.
Disclosure
Aethir Foundation is Axe Compute's shareholder, through its 2025 treasury transaction. We cover Axe as an interested holder. This article reflects Aethir's views and is not investment advice. For official company information, see Axe Compute's SEC filings (CIK 0001446159) and investors.axecompute.com.
Nothing in this article should be relied upon as a guarantee of future performance or results.
Frequently Asked Questions
Who is Axe Compute’s strategic AI infrastructure partner?
Penguin Solutions. Axe Compute signed it as a multi-year strategic partner to accelerate Axe Compute Build, supporting multiple sites with deployment and operational services, ClusterWareAI software, and 24x7 network operations center coverage. Axe Compute keeps the customer contracts, capital, and asset ownership.
What does cluster lifecycle management cover?
Cluster lifecycle management covers everything after the hardware arrives: integration, burn-in, validation, monitoring, remediation, and upgrades. It’s the half of GPU cluster operations that decides whether a cluster stays available once it’s live, which is why operators buy it rather than build it.
How fast can a multi-thousand-GPU cluster reach production?
Power, site readiness, and integration decide most of it. The honest answer is a range. The reference point here is the Haein sovereign AI cluster, which Penguin reports was production-ready within weeks of the hardware arriving on site. Validated architectures and factory burn-in are what compress that window.